Benchmarks and verification
Poisson regression scale validation and performance
The standard benchmark compares the release PHP extension, R glm(poisson) and statsmodels GLM on identical synthetic observations. The raw report preserves all timing samples, machine and runtime versions, input hashes, numerical outputs and differences from R.
Recorded results
from pathlib import Path
import json
import pandas as pd

# Keep display order independent of the benchmark worker execution order.
def ordered_table(rows):
    table = pd.DataFrame(rows)
    table["implementation"] = pd.Categorical(
        table["implementation"], categories=["R", "statsmodels", "PHP"], ordered=True)
    return table.sort_values(["observations", "coefficients", "implementation"]).reset_index(drop=True)

ROOT = next(p for p in [Path.cwd(), *Path.cwd().parents] if (p / "Cargo.toml").exists())
report = json.loads((ROOT / "docs/benchmarks/poisson-results.json").read_text())
assert report["model"] == "poisson"
print("Recorded:", report["recorded_at"])
print("Machine:", report["cpu"], report["platform"])
print("Rust:", report["rust"])
print("Repeats:", report["repeats"], "Warm-ups:", report["warmups"])
rows, memory = [], []
for case in report["cases"]:
    assert case["agreement_passed"]
    for name, fit in case["implementations"].items():
        rows.append({"observations": case["n"], "coefficients": case["p"],
                     "implementation": name, "version": fit["version"],
                     "median full fit (ms)": 1000*fit["median_fit_seconds"],
                     "minimum full fit (ms)": 1000*fit["min_fit_seconds"]})
        memory.append({"observations": case["n"], "coefficients": case["p"],
                       "implementation": name, "CSV load (s)": fit["load_seconds"],
                       "whole process (s)": fit["process_seconds"],
                       "peak process RSS (MiB)": fit["peak_rss_bytes"]/2**20 if fit["peak_rss_bytes"] else None})
display(ordered_table(rows))
Recorded: 2026-10-16T07:51:11.086697+00:00
Machine: Apple M5 Ultra macOS-27.0.1-arm64-arm-64bit-Mach-O
Rust: rustc 1.99.0 (b940084d7 2026-09-28) (Homebrew)
Repeats: 5 Warm-ups: 1| observations | coefficients | implementation | version | median full fit (ms) | minimum full fit (ms) | |
|---|---|---|---|---|---|---|
| 0 | 1000 | 3 | R | R version 4.6.1 (2026-06-24) | 2.000000 | 1.000000 |
| 1 | 1000 | 3 | statsmodels | 0.15.0 | 0.766834 | 0.742791 |
| 2 | 1000 | 3 | PHP | 8.5.10 | 0.244667 | 0.240708 |
| 3 | 100000 | 3 | R | R version 4.6.1 (2026-06-24) | 135.000000 | 130.000000 |
| 4 | 100000 | 3 | statsmodels | 0.15.0 | 31.078417 | 30.588917 |
| 5 | 100000 | 3 | PHP | 8.5.10 | 26.229333 | 25.544417 |
| 6 | 100000 | 11 | R | R version 4.6.1 (2026-06-24) | 283.000000 | 274.000000 |
| 7 | 100000 | 11 | statsmodels | 0.15.0 | 68.415666 | 67.694792 |
| 8 | 100000 | 11 | PHP | 8.5.10 | 69.535750 | 67.548459 |
| 9 | 1000000 | 3 | R | R version 4.6.1 (2026-06-24) | 1437.000000 | 1322.000000 |
| 10 | 1000000 | 3 | statsmodels | 0.15.0 | 328.982667 | 327.916083 |
| 11 | 1000000 | 3 | PHP | 8.5.10 | 277.840083 | 268.567584 |
The cases include 1,000, 100,000 and one million observations with three coefficients, and 100,000 observations with eleven coefficients. Counts include the intercept. These measurements describe this workload and environment, not a universal ranking. The raw report preserves each repetition.
Visual comparison
benchmarks/figures/poisson-fit-time.svg
benchmarks/figures/poisson-memory.svg 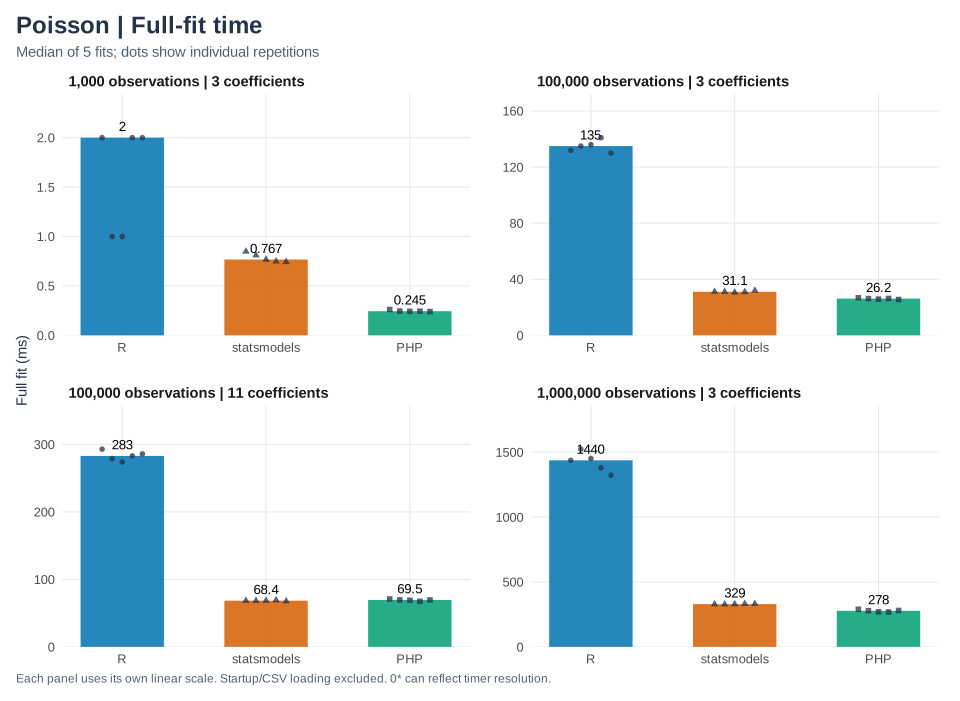
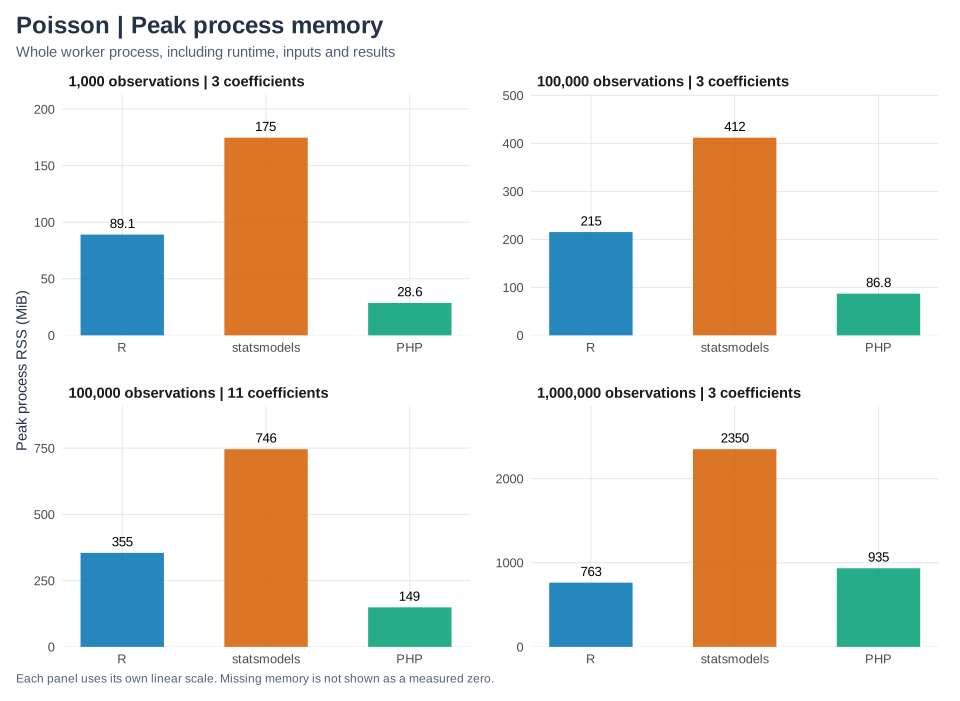
R, statsmodels and PHP use the same order and colors throughout. Each panel has its own linear scale so small workloads remain readable; compare labeled values across panels. Memory covers the entire worker process. It is not the solver’s allocation count. All workloads passed the numerical checks described below.
Download the timing SVG or PNG, and memory SVG or PNG. Charts refresh from saved measurements when this page is executed; they do not rerun the benchmarks.
What is timed?
Workers load the same CSV once, perform one untimed warm-up, and measure five full fits. Each timed fit materializes coefficients, covariance, standard errors, normal z tests, p-values, Wald intervals, every fitted mean count and response residual, likelihood, deviance, null deviance, AIC and residual degrees of freedom. PHP also converts inputs and all outputs and constructs row metadata within the timer. Startup, CSV loading, data generation and final JSON serialization are excluded.
R uses formula/model construction and QR-based IRLS, with epsilon 1e-16 to stabilize covariance agreement. Python uses GLM IRLS with parameter tolerance 1e-11; PHP uses weighted SVD Newton updates and its documented convergence rules. Starting values, linear solves and stopping criteria differ. This is a comparison of complete public API calls, not equal iteration counts or isolated decomposition speeds. Common numerical-library thread variables are set to one; installed backends and requested settings are recorded. Workers run separately with order alternated between cases. Other machine activity can affect measurements. R’s elapsed timer has coarse millisecond resolution for small cases.
display(ordered_table(memory))| observations | coefficients | implementation | CSV load (s) | whole process (s) | peak process RSS (MiB) | |
|---|---|---|---|---|---|---|
| 0 | 1000 | 3 | R | 0.001000 | 0.166073 | 89.078125 |
| 1 | 1000 | 3 | statsmodels | 0.000316 | 0.663927 | 174.750000 |
| 2 | 1000 | 3 | PHP | 0.000613 | 0.046898 | 28.625000 |
| 3 | 100000 | 3 | R | 0.047000 | 1.071532 | 215.171875 |
| 4 | 100000 | 3 | statsmodels | 0.014608 | 0.859887 | 411.875000 |
| 5 | 100000 | 3 | PHP | 0.056039 | 0.259662 | 86.828125 |
| 6 | 100000 | 11 | R | 0.482000 | 2.560594 | 354.687500 |
| 7 | 100000 | 11 | statsmodels | 0.104589 | 1.209845 | 745.906250 |
| 8 | 100000 | 11 | PHP | 0.276801 | 0.743030 | 149.265625 |
| 9 | 1000000 | 3 | R | 0.759000 | 9.663629 | 763.046875 |
| 10 | 1000000 | 3 | statsmodels | 0.142587 | 2.808749 | 2350.703125 |
| 11 | 1000000 | 3 | PHP | 0.580065 | 2.342486 | 934.718750 |
Whole-process time includes loading, imports, warm-up and every measured fit. Peak resident memory covers the entire worker, not just the numerical solver. PHP memory_limit is disabled for this experiment because large nested PHP arrays can exceed typical application limits. See the OLS benchmark for the shared harness and further interpretation of these boundaries.
Simulation and agreement
NumPy RNG seed 20261011 first draws the common benchmark setup, then generates integer visitor counts uniformly from 80 to 300 and staffing as clipped visitors/50 plus normal noise with standard deviation 0.8. Wider models add independent standard-normal scores. Count outcomes are draws from
\[\mu_i=\exp(0.1+0.005\,\mathrm{visitors}_i-0.12\,\mathrm{staff}_i +0.1\sum_j\mathrm{extra}_{ij}),\qquad y_i\sim\operatorname{Poisson}(\mu_i).\]
This simulation is separate from the small R-generated teaching sample; its scores are unrounded and its seed is different. Every runtime reads identical 17-significant-digit CSV values. Data hashes, generating coefficients and sample correlations are recorded. All coefficient-level quantities and scalar statistics are compared with R at tolerance 1e-9 + 1e-7 × abs(reference). Full fitted/residual vectors are materialized; cross-runtime comparison samples ten evenly spaced rows, while small fixtures check complete vectors. PHP convergence must be true and its update count must be between one and 100. Wald intervals use R confint.default(), and the null baseline follows the documented intercept convention. Poisson deviance uses the saturated count likelihood, not -2 log-likelihood.
display(ordered_table([{ "observations": case["n"], "coefficients": case["p"],
                        "implementation": name, "largest absolute difference vs R": max(errors.values())}
                       for case in report["cases"]
for name, errors in case["max_absolute_errors_vs_R"].items()]))| observations | coefficients | implementation | largest absolute difference vs R | |
|---|---|---|---|---|
| 0 | 1000 | 3 | statsmodels | 1.200995e-11 |
| 1 | 1000 | 3 | PHP | 4.774847e-12 |
| 2 | 100000 | 3 | statsmodels | 3.479363e-08 |
| 3 | 100000 | 3 | PHP | 5.398761e-09 |
| 4 | 100000 | 11 | statsmodels | 6.420305e-08 |
| 5 | 100000 | 11 | PHP | 1.478475e-08 |
| 6 | 1000000 | 3 | statsmodels | 1.622131e-06 |
| 7 | 1000000 | 3 | PHP | 4.051253e-08 |
Reproduce
export PHP=/opt/homebrew/bin/php
export PHP_CONFIG=/opt/homebrew/bin/php-config
cargo build -p php-stats --release --locked
.context/notebooks-venv/bin/python tests/benchmarks/run.py --model poisson
QUARTO_PYTHON="$PWD/.context/notebooks-venv/bin/python" quarto render docs/benchmarks/poisson.qmd
quarto render docs
Select matching PHP tools and .so on Linux. Use --cases 1000:3 --repeats 2 --output .context/poisson-smoke.json for a quick check that preserves the published report. Numerical failures abort without publishing results. Benchmarks are explicit development commands; ordinary renders and tests read saved evidence. Optimization or additional numerical dependencies should answer a demonstrated need.
From phpstats/phit@76b22f0.