Benchmarks and verification
Gaussian mixed models on four published datasets
We verify the optimized random-intercept ML implementation on four published datasets, in addition to the synthetic fixtures, closed-form variance test and million-row benchmarks. Every model uses the same explicit fixed columns and observations in R lme4, R nlme, Python statsmodels and PHP. Data provenance, original research references, CSV downloads and checksums are in the data-source record.
These are numerical comparisons of the specified models. They do not establish that a random intercept adequately models each scientific study. In particular, we do not reproduce the random-slope sleepstudy example or a worker-by-machine interaction. All fits are marginal maximum likelihood, not REML.
Execute all four comparisons
from pathlib import Path
import json,sys
import numpy as np
import pandas as pd

from IPython.display import display
ROOT=next(p for p in [Path.cwd(),*Path.cwd().parents] if (p/'Cargo.toml').exists())
import sys
sys.path.insert(0,str(ROOT/'docs/figures'))
from bridge import render_figure
sys.path.insert(0,str(ROOT/'docs/verifications'))
from compare_lmm import public_cases,compare_case
cases=public_cases()
results=[compare_case(case,include_nlme=True) for case in cases]
ORDER=[('R','R: lme4'),('nlme','R: nlme'),('Python','statsmodels'),('php-stats','PHP')]
print('Versions:',results[0]['versions'])
display(pd.DataFrame([dict(dataset=c['name'],observations=len(c['y']),groups=len(set(c['groups'])),
                           fixed_coefficients=len(c['x'][0]),formula=c['source']['formula'],
                           all_comparisons_passed=True) for c in cases]))
Versions: {'R': 'R version 4.6.1 (2026-06-24)', 'lme4': '2.0.6', 'statsmodels': '0.15.0', 'PHP': '8.5.10', 'Python': '3.14.7', 'nlme': '3.1.169'}| dataset | observations | groups | fixed_coefficients | formula | all_comparisons_passed | |
|---|---|---|---|---|---|---|
| 0 | sleepstudy | 180 | 18 | 2 | Reaction ~ Days + (1 | Subject) | True |
| 1 | Orthodont | 108 | 27 | 4 | distance ~ age * female + (1 | Subject) | True |
| 2 | Machines | 54 | 6 | 3 | score ~ machine_B + machine_C + (1 | Worker) | True |
| 3 | Hsb82 | 7185 | 160 | 4 | mAch ~ ses + meanses + catholic + (1 | school) | True |
The runner checks every row, not a sample: population and conditional fitted values, both residual definitions, all group effects, coefficients, covariance, standard errors, normal Wald tests/intervals, variance components, ICC, likelihood and AIC. Group labels, ordering, retained rows and observation counts are exact. Both R packages supply independent model estimates. statsmodels supplies its own ML estimates; its fixed-effect covariance is recomputed as plug-in GLS to match lme4 and our contract. All Python mixed fits must converge; warnings are retained. Both R references use vcov() and explicit normal Wald calculations to match our declared inference. Default nlme t-tests and profile-likelihood intervals use different conventions.
Estimates by dataset
Reaction ~ Days + (1 | Subject), all 180 observations.
| implementation | term | estimate | SE | z | p | lower95 | upper95 | |
|---|---|---|---|---|---|---|---|---|
| 0 | R: lme4 | intercept | 251.405105 | 9.506185 | 26.446477 | 4.005641e-154 | 232.773324 | 270.036886 |
| 1 | R: lme4 | Days | 10.467286 | 0.801735 | 13.055786 | 5.889911e-39 | 8.895913 | 12.038659 |
| 2 | R: nlme | intercept | 251.405105 | 9.506185 | 26.446477 | 4.005631e-154 | 232.773324 | 270.036885 |
| 3 | R: nlme | Days | 10.467286 | 0.801735 | 13.055786 | 5.889912e-39 | 8.895913 | 12.038659 |
| 4 | statsmodels | intercept | 251.405105 | 9.506185 | 26.446477 | 4.005628e-154 | 232.773324 | 270.036885 |
| 5 | statsmodels | Days | 10.467286 | 0.801735 | 13.055786 | 5.889912e-39 | 8.895913 | 12.038659 |
| 6 | PHP | intercept | 251.405105 | 9.506185 | 26.446477 | 4.005628e-154 | 232.773324 | 270.036885 |
| 7 | PHP | Days | 10.467286 | 0.801735 | 13.055786 | 5.889912e-39 | 8.895913 | 12.038659 |
distance ~ age * female + (1 | Subject), all 108 observations. The age × female column is constructed before calling the library.
| implementation | term | estimate | SE | z | p | lower95 | upper95 | |
|---|---|---|---|---|---|---|---|---|
| 0 | R: lme4 | intercept | 16.340625 | 0.963085 | 16.966962 | 1.442018e-64 | 14.453013 | 18.228237 |
| 1 | R: lme4 | age | 0.784375 | 0.076538 | 10.248134 | 1.206497e-24 | 0.634363 | 0.934387 |
| 2 | R: lme4 | female | 1.032102 | 1.508864 | 0.684026 | 4.939587e-01 | -1.925217 | 3.989422 |
| 3 | R: lme4 | age × female | -0.304830 | 0.119913 | -2.542100 | 1.101887e-02 | -0.539854 | -0.069805 |
| 4 | R: nlme | intercept | 16.340625 | 0.963085 | 16.966962 | 1.442018e-64 | 14.453013 | 18.228237 |
| 5 | R: nlme | age | 0.784375 | 0.076538 | 10.248135 | 1.206495e-24 | 0.634363 | 0.934387 |
| 6 | R: nlme | female | 1.032102 | 1.508864 | 0.684026 | 4.939587e-01 | -1.925217 | 3.989422 |
| 7 | R: nlme | age × female | -0.304830 | 0.119913 | -2.542100 | 1.101887e-02 | -0.539854 | -0.069805 |
| 8 | statsmodels | intercept | 16.340625 | 0.963085 | 16.966962 | 1.442018e-64 | 14.453013 | 18.228237 |
| 9 | statsmodels | age | 0.784375 | 0.076538 | 10.248134 | 1.206497e-24 | 0.634363 | 0.934387 |
| 10 | statsmodels | female | 1.032102 | 1.508864 | 0.684026 | 4.939587e-01 | -1.925217 | 3.989422 |
| 11 | statsmodels | age × female | -0.304830 | 0.119913 | -2.542100 | 1.101887e-02 | -0.539854 | -0.069805 |
| 12 | PHP | intercept | 16.340625 | 0.963085 | 16.966962 | 1.442018e-64 | 14.453013 | 18.228237 |
| 13 | PHP | age | 0.784375 | 0.076538 | 10.248134 | 1.206497e-24 | 0.634363 | 0.934387 |
| 14 | PHP | female | 1.032102 | 1.508864 | 0.684026 | 4.939587e-01 | -1.925217 | 3.989422 |
| 15 | PHP | age × female | -0.304830 | 0.119913 | -2.542100 | 1.101887e-02 | -0.539854 | -0.069805 |
score ~ machine_B + machine_C + (1 | Worker), all 54 observations. Machine A is the reference brand.
| implementation | term | estimate | SE | z | p | lower95 | upper95 | |
|---|---|---|---|---|---|---|---|---|
| 0 | R: lme4 | intercept | 52.355556 | 2.046413 | 25.584062 | 2.295299e-144 | 48.344660 | 56.366451 |
| 1 | R: lme4 | machine B | 7.966667 | 1.031693 | 7.721935 | 1.145765e-14 | 5.944586 | 9.988748 |
| 2 | R: lme4 | machine C | 13.916667 | 1.031693 | 13.489155 | 1.811651e-41 | 11.894586 | 15.938748 |
| 3 | R: nlme | intercept | 52.355556 | 2.046413 | 25.584061 | 2.295327e-144 | 48.344660 | 56.366451 |
| 4 | R: nlme | machine B | 7.966667 | 1.031693 | 7.721935 | 1.145764e-14 | 5.944586 | 9.988748 |
| 5 | R: nlme | machine C | 13.916667 | 1.031693 | 13.489155 | 1.811650e-41 | 11.894586 | 15.938748 |
| 6 | statsmodels | intercept | 52.355556 | 2.046413 | 25.584062 | 2.295309e-144 | 48.344660 | 56.366451 |
| 7 | statsmodels | machine B | 7.966667 | 1.031693 | 7.721935 | 1.145764e-14 | 5.944586 | 9.988748 |
| 8 | statsmodels | machine C | 13.916667 | 1.031693 | 13.489155 | 1.811650e-41 | 11.894586 | 15.938748 |
| 9 | PHP | intercept | 52.355556 | 2.046413 | 25.584062 | 2.295309e-144 | 48.344660 | 56.366451 |
| 10 | PHP | machine B | 7.966667 | 1.031693 | 7.721935 | 1.145764e-14 | 5.944586 | 9.988748 |
| 11 | PHP | machine C | 13.916667 | 1.031693 | 13.489155 | 1.811650e-41 | 11.894586 | 15.938748 |
mAch ~ ses + meanses + catholic + (1 | school), all 7,185 observations. Public schools are the reference sector.
| implementation | term | estimate | SE | z | p | lower95 | upper95 | |
|---|---|---|---|---|---|---|---|---|
| 0 | R: lme4 | intercept | 12.128223 | 0.197301 | 61.470575 | 0.000000e+00 | 11.741520 | 12.514927 |
| 1 | R: lme4 | SES | 2.191172 | 0.108666 | 20.164274 | 2.016856e-90 | 1.978190 | 2.404154 |
| 2 | R: lme4 | school mean SES | 3.143956 | 0.381147 | 8.248675 | 1.601605e-16 | 2.396922 | 3.890990 |
| 3 | R: lme4 | Catholic school | 1.224874 | 0.303067 | 4.041598 | 5.308810e-05 | 0.630874 | 1.818874 |
| 4 | R: nlme | intercept | 12.128223 | 0.197301 | 61.470580 | 0.000000e+00 | 11.741520 | 12.514927 |
| 5 | R: nlme | SES | 2.191172 | 0.108666 | 20.164274 | 2.016857e-90 | 1.978190 | 2.404154 |
| 6 | R: nlme | school mean SES | 3.143956 | 0.381147 | 8.248675 | 1.601597e-16 | 2.396922 | 3.890990 |
| 7 | R: nlme | Catholic school | 1.224874 | 0.303067 | 4.041599 | 5.308802e-05 | 0.630874 | 1.818874 |
| 8 | statsmodels | intercept | 12.128223 | 0.197301 | 61.470578 | 0.000000e+00 | 11.741520 | 12.514927 |
| 9 | statsmodels | SES | 2.191172 | 0.108666 | 20.164274 | 2.016857e-90 | 1.978190 | 2.404154 |
| 10 | statsmodels | school mean SES | 3.143956 | 0.381147 | 8.248675 | 1.601601e-16 | 2.396922 | 3.890990 |
| 11 | statsmodels | Catholic school | 1.224874 | 0.303067 | 4.041599 | 5.308806e-05 | 0.630874 | 1.818874 |
| 12 | PHP | intercept | 12.128223 | 0.197301 | 61.470578 | 0.000000e+00 | 11.741520 | 12.514927 |
| 13 | PHP | SES | 2.191172 | 0.108666 | 20.164274 | 2.016857e-90 | 1.978190 | 2.404154 |
| 14 | PHP | school mean SES | 3.143956 | 0.381147 | 8.248675 | 1.601601e-16 | 2.396922 | 3.890990 |
| 15 | PHP | Catholic school | 1.224874 | 0.303067 | 4.041599 | 5.308806e-05 | 0.630874 | 1.818874 |
Variances and likelihood
rows=[]
for result in results:
    for key,label in ORDER:
        fit=result[key]
        rows.append(dict(dataset=result['name'],implementation=label,
                         residual_variance=fit['residual_variance'],group_variance=fit['random_intercept_variance'],
                         ICC=fit['icc'],log_likelihood=fit['log_likelihood'],AIC=fit['aic']))
display(pd.DataFrame(rows))| dataset | implementation | residual_variance | group_variance | ICC | log_likelihood | AIC | |
|---|---|---|---|---|---|---|---|
| 0 | sleepstudy | R: lme4 | 954.527833 | 1296.870056 | 0.576029 | -897.039322 | 1802.078643 |
| 1 | sleepstudy | R: nlme | 954.527834 | 1296.870044 | 0.576029 | -897.039322 | 1802.078643 |
| 2 | sleepstudy | statsmodels | 954.527835 | 1296.870040 | 0.576029 | -897.039322 | 1802.078643 |
| 3 | sleepstudy | PHP | 954.527835 | 1296.870040 | 0.576029 | -897.039322 | 1802.078643 |
| 4 | Orthodont | R: lme4 | 1.874597 | 3.030562 | 0.617832 | -214.319529 | 440.639058 |
| 5 | Orthodont | R: nlme | 1.874597 | 3.030562 | 0.617832 | -214.319529 | 440.639058 |
| 6 | Orthodont | statsmodels | 1.874597 | 3.030562 | 0.617832 | -214.319529 | 440.639058 |
| 7 | Orthodont | PHP | 1.874597 | 3.030562 | 0.617832 | -214.319529 | 440.639058 |
| 8 | Machines | R: lme4 | 9.579514 | 21.933665 | 0.696016 | -146.851628 | 303.703256 |
| 9 | Machines | R: nlme | 9.579514 | 21.933666 | 0.696016 | -146.851628 | 303.703256 |
| 10 | Machines | statsmodels | 9.579514 | 21.933665 | 0.696016 | -146.851628 | 303.703256 |
| 11 | Machines | PHP | 9.579514 | 21.933665 | 0.696016 | -146.851628 | 303.703256 |
| 12 | Hsb82 | R: lme4 | 37.018217 | 2.306017 | 0.058641 | -23274.159698 | 46560.319397 |
| 13 | Hsb82 | R: nlme | 37.018217 | 2.306017 | 0.058641 | -23274.159698 | 46560.319397 |
| 14 | Hsb82 | statsmodels | 37.018217 | 2.306017 | 0.058641 | -23274.159698 | 46560.319397 |
| 15 | Hsb82 | PHP | 37.018217 | 2.306017 | 0.058641 | -23274.159698 | 46560.319397 |
Look closely at numerical differences
The graph shows the difference between native and lme4 conditional fitted values, scaled by a million to make rounding differences visible. Zero means exact agreement. Every point is a retained observation; panel units differ by dataset. It is a numerical agreement plot, not a model residual diagnostic.
figures/lmm-public-agreement.svg 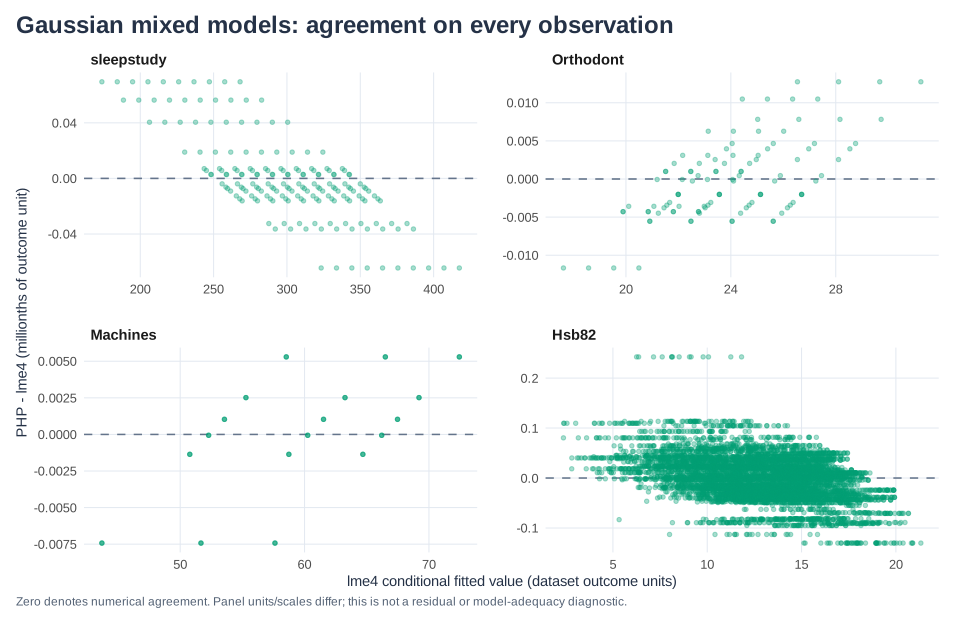
| dataset | largest_native_residual_difference_vs_lme4 | largest_native_log_likelihood_difference_vs_lme4 | largest_native_residual_difference_vs_statsmodels | |
|---|---|---|---|---|
| 0 | sleepstudy | 6.950341e-08 | 1.136868e-13 | 3.489049e-10 |
| 1 | Orthodont | 1.275022e-08 | 8.526513e-14 | 3.197442e-14 |
| 2 | Machines | 7.426245e-09 | 2.842171e-14 | 3.324629e-11 |
| 3 | Hsb82 | 2.423659e-07 | 7.275958e-12 | 4.600764e-13 |
Default public-data tolerances are 1e-7 absolute plus 1e-6 relative. The four observation-length output vectors use 1e-6 absolute in their outcome’s units, plus 1e-6 relative, so residuals close to zero are not tested by relative error alone. Likelihood and AIC use 1e-7 absolute plus 1e-10 relative. Original synthetic fixtures retain their uniform 1e-7 + 1e-6 × abs(reference) tolerance. These policies are recorded with each source fixture and live report. An additional native-versus-statsmodels check keeps the stricter original uniform tolerance for all quantities; reference-optimizer rounding allowances cannot hide divergence between those two estimates.
The High School and Beyond sample illustrates an optimizer precision limit: lme4 and nlme have effectively identical likelihoods but slightly different variance estimates. Conditional residual differences can reach a few 1e-7 when the residual itself is nearly zero. The profile scores below independently check stationarity at each estimate; they are derivatives of negative profile log-likelihood with respect to log(1 + tau²/sigma²). Zero is the interior optimum condition. Raw scores depend on dataset size and curvature and should not be compared across different studies as a universal error metric.
display(pd.DataFrame([dict(dataset=r['name'],implementation=label,
                           profile_score=r['profile_scores'][key],
                           log_likelihood_difference_vs_lme4=r[key]['log_likelihood']-r['R']['log_likelihood'])
                      for r in results for key,label in ORDER]))
for result in results:
print(result['name'],'Python warnings:',result['python_diagnostics']['warnings'])| dataset | implementation | profile_score | log_likelihood_difference_vs_lme4 | |
|---|---|---|---|---|
| 0 | sleepstudy | R: lme4 | 1.594587e-07 | 0.000000e+00 |
| 1 | sleepstudy | R: nlme | 3.946868e-08 | -2.273737e-13 |
| 2 | sleepstudy | statsmodels | -7.970267e-10 | -1.136868e-13 |
| 3 | sleepstudy | PHP | 3.542481e-12 | -1.136868e-13 |
| 4 | Orthodont | R: lme4 | -2.981962e-07 | 0.000000e+00 |
| 5 | Orthodont | R: nlme | 1.549555e-06 | -1.705303e-13 |
| 6 | Orthodont | statsmodels | -1.942906e-12 | -1.136868e-13 |
| 7 | Orthodont | PHP | -1.457179e-12 | -8.526513e-14 |
| 8 | Machines | R: lme4 | -6.462817e-08 | 0.000000e+00 |
| 9 | Machines | R: nlme | 1.087264e-07 | 0.000000e+00 |
| 10 | Machines | statsmodels | -2.902163e-10 | -2.842171e-14 |
| 11 | Machines | PHP | -9.890258e-13 | -2.842171e-14 |
| 12 | Hsb82 | R: lme4 | 8.646686e-05 | 0.000000e+00 |
| 13 | Hsb82 | R: nlme | -7.109857e-05 | -3.637979e-12 |
| 14 | Hsb82 | statsmodels | -2.725753e-10 | -7.275958e-12 |
| 15 | Hsb82 | PHP | -4.321110e-10 | -7.275958e-12 |
sleepstudy Python warnings: []
Orthodont Python warnings: []
Machines Python warnings: []
Hsb82 Python warnings: []
Reproduce without fetching data
The CSVs and lme4/nlme expected outputs are checked into the repository. cargo test --workspace and tests/lmm.php check the published fixtures without R, Python or network access. The live comparison requires lme4, nlme and the pinned Python environment, but not mlmRev: it reads the saved Hsb82 CSV.
cargo test --workspace --locked
PHP=/opt/homebrew/bin/php STATS_EXTENSION="$PWD/target/release/libphp_stats.dylib" \
  .context/notebooks-venv/bin/python docs/verifications/compare_lmm.py --public
QUARTO_PYTHON="$PWD/.context/notebooks-venv/bin/python" PHP=/opt/homebrew/bin/php \
  quarto render docs/notebooks/lmm-public-verification.qmd
Use matching PHP headers to build the extension first; use .so on Linux. The saved live report records full outputs, source checksums, runtime versions, the extension hash, warnings, tolerances and score/error checks. Re-execute this page after statistical-code or source-data changes; merely rendering saved outputs is not new verification.
This strengthens evidence for the current Gaussian random-intercept ML model. It does not establish correctness for random slopes, REML, other response families, assumption checks, or finite-sample group-level inference.
From phpstats/phit@76b22f0.